Yongchang Zhang张用长
Incoming Ph.D. Student · Fall 2027
Member of PKU-VaLuE Lab
Advised by Prof. Yiwu Zhong, Peking University
Embodied AI VLA World Action Models VLMs

About
I am an incoming Ph.D. student (Fall 2027) and a member of the PKU-VaLuE Lab (Vision-Language and Embodied AI), advised by Prof. Yiwu Zhong at Peking University. My current research focuses on embodied AI, in particular vision-language-action (VLA) models and world action models (WAMs).
I am completing my B.Eng. in Software Engineering at Southeast University, where I am fortunate to be advised by Prof. Yang Chen (School of Computer Science and Engineering) and Prof. Guangquan Zhou (School of Biological Science and Medical Engineering). There I worked on medical image analysis and vision-language models, including training-free methods for visually grounded multimodal reasoning.
News
- 2026Joined the PKU-VaLuE Lab, advised by Prof. Yiwu Zhong.
- 2026.02See It, Say It, Sorted is accepted to CVPR 2026.
Publications* equal contribution
-
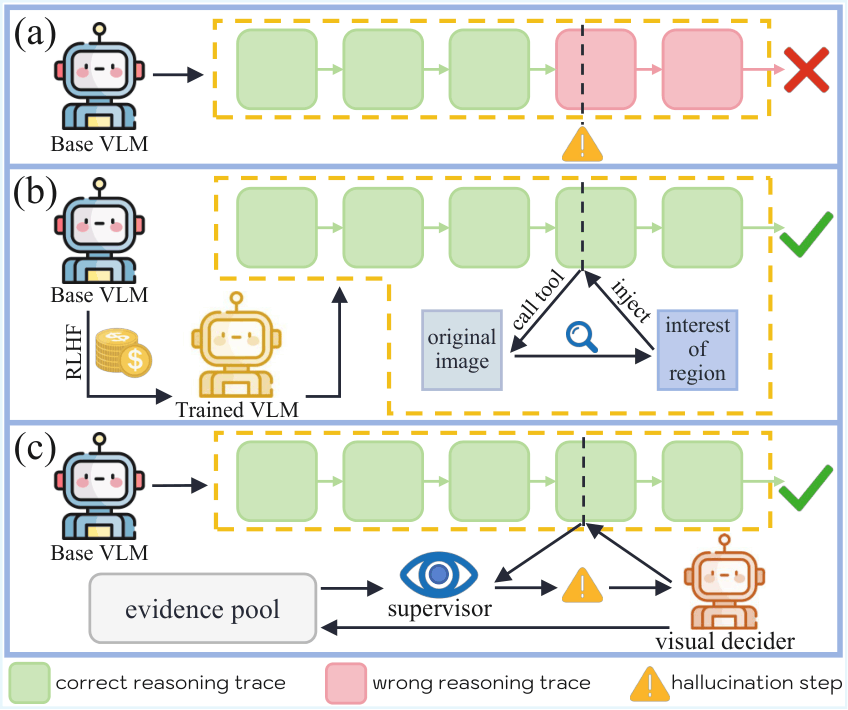
A plug-and-play decoding method that checks each reasoning step against visual evidence to curb hallucination in LVLMs, with no extra training.
Full list on Google Scholar
Education
-
2023 – 2027
Southeast University
B.Eng. in Software Engineering
Advisors: Prof. Yang Chen & Prof. Guangquan Zhou